Model Gallery

Discover and install AI models from our curated collection

197 models available
1 repositories
Documentation

Find Your Perfect Model

Filter by Model Type

Browse by Tags

deepseek-v4.1-flash-ista-iq2_xs
DeepSeek-V4.1-Flash-1017, a 763B-parameter mixture-of-experts model (384 experts per layer, 6 used per token), in ISTA-DAS's 2.25 bits per weight GSQ-RCO quantization (IQ2_XS), the largest size of the three (about 274 GB to download). It writes a reasoning trace before the answer, and the Strata backend splits it from the reply and parses the model's DSML tool calls. Text only: images are not supported by this backend. Needs a GPU with 12 GB of VRAM or more and about 44 GB of RAM at the least (Strata's figure; its measurements use 46 to 64 GB: an RTX 5070 with 64 GB answered at about 5 tokens per second, an RTX 3060 with 46 GB at 8 to 10). Less RAM still runs, slowly. Strata measured a perplexity 7.3% above the original model on 4,995 positions (code 3.2%, agent work 2.2%). Needs about 275 GB of free disk, on a fast NVMe drive: the 111 GB n-gram table (Engram) stays on disk and is read for every token. The Engram table and the 8 GB DSpark draft model are shared by all DeepSeek-V4.1 entries and downloaded once into strata/models/deepseek-v4.1-flash-shared. Runs only on the experimental strata backend, on NVIDIA CUDA 13 (x86_64 and arm64), AMD Radeon RX 9070 and R9700 (ROCm) and Apple Silicon (Metal). Strata ships no DeepSeek engine for CUDA 12, Intel or other AMD cards. On the first load the strata backend builds the Strata pack from the GGUF files (under a minute, a few MB of extra disk); loading the model afterwards takes a few minutes. The default context is 8192 tokens, the size Strata checked; raise context_size if the GPU has room. Licensed under the MIT License (DeepSeek-V4.1-Flash-1017 and the quantized files). The GGUF files are the GSQ-RCO quantization by ISTA-DAS (ISTA-DASLab); the DSpark draft model is Unsloth's; Strata is by Niko1221.

Repository: localaiLicense: mit

bge-large-en-v1.5-f16
BGE-large-en-v1.5 is a 335M English embedding model for semantic search and retrieval. This F16 GGUF build produces 1024-dimensional embeddings with a 512-token context. For retrieval, prefix queries with "Represent this sentence for searching relevant passages: "; leave passages unprefixed.

Repository: localaiLicense: mit

bge-large-en-v1.5-q8-0
BGE-large-en-v1.5 is a 335M English embedding model for semantic search and retrieval. This Q8_0 GGUF build produces 1024-dimensional embeddings with a 512-token context. For retrieval, prefix queries with "Represent this sentence for searching relevant passages: "; leave passages unprefixed.

Repository: localaiLicense: mit

bge-large-en-v1.5-q4-k-m
BGE-large-en-v1.5 is a 335M English embedding model for semantic search and retrieval. This Q4_K_M GGUF build produces 1024-dimensional embeddings with a 512-token context. For retrieval, prefix queries with "Represent this sentence for searching relevant passages: "; leave passages unprefixed.

Repository: localaiLicense: mit

bge-large-en-v1.5-transformers
BGE-large-en-v1.5 is a 335M English embedding model for semantic search and retrieval. This safetensors build uses the Transformers backend's SentenceTransformer loader, producing 1024-dimensional embeddings with a 512-token context. For retrieval, prefix queries with "Represent this sentence for searching relevant passages: "; leave passages unprefixed.

Repository: localaiLicense: mit

qwen3.8-flash-next-uncensored
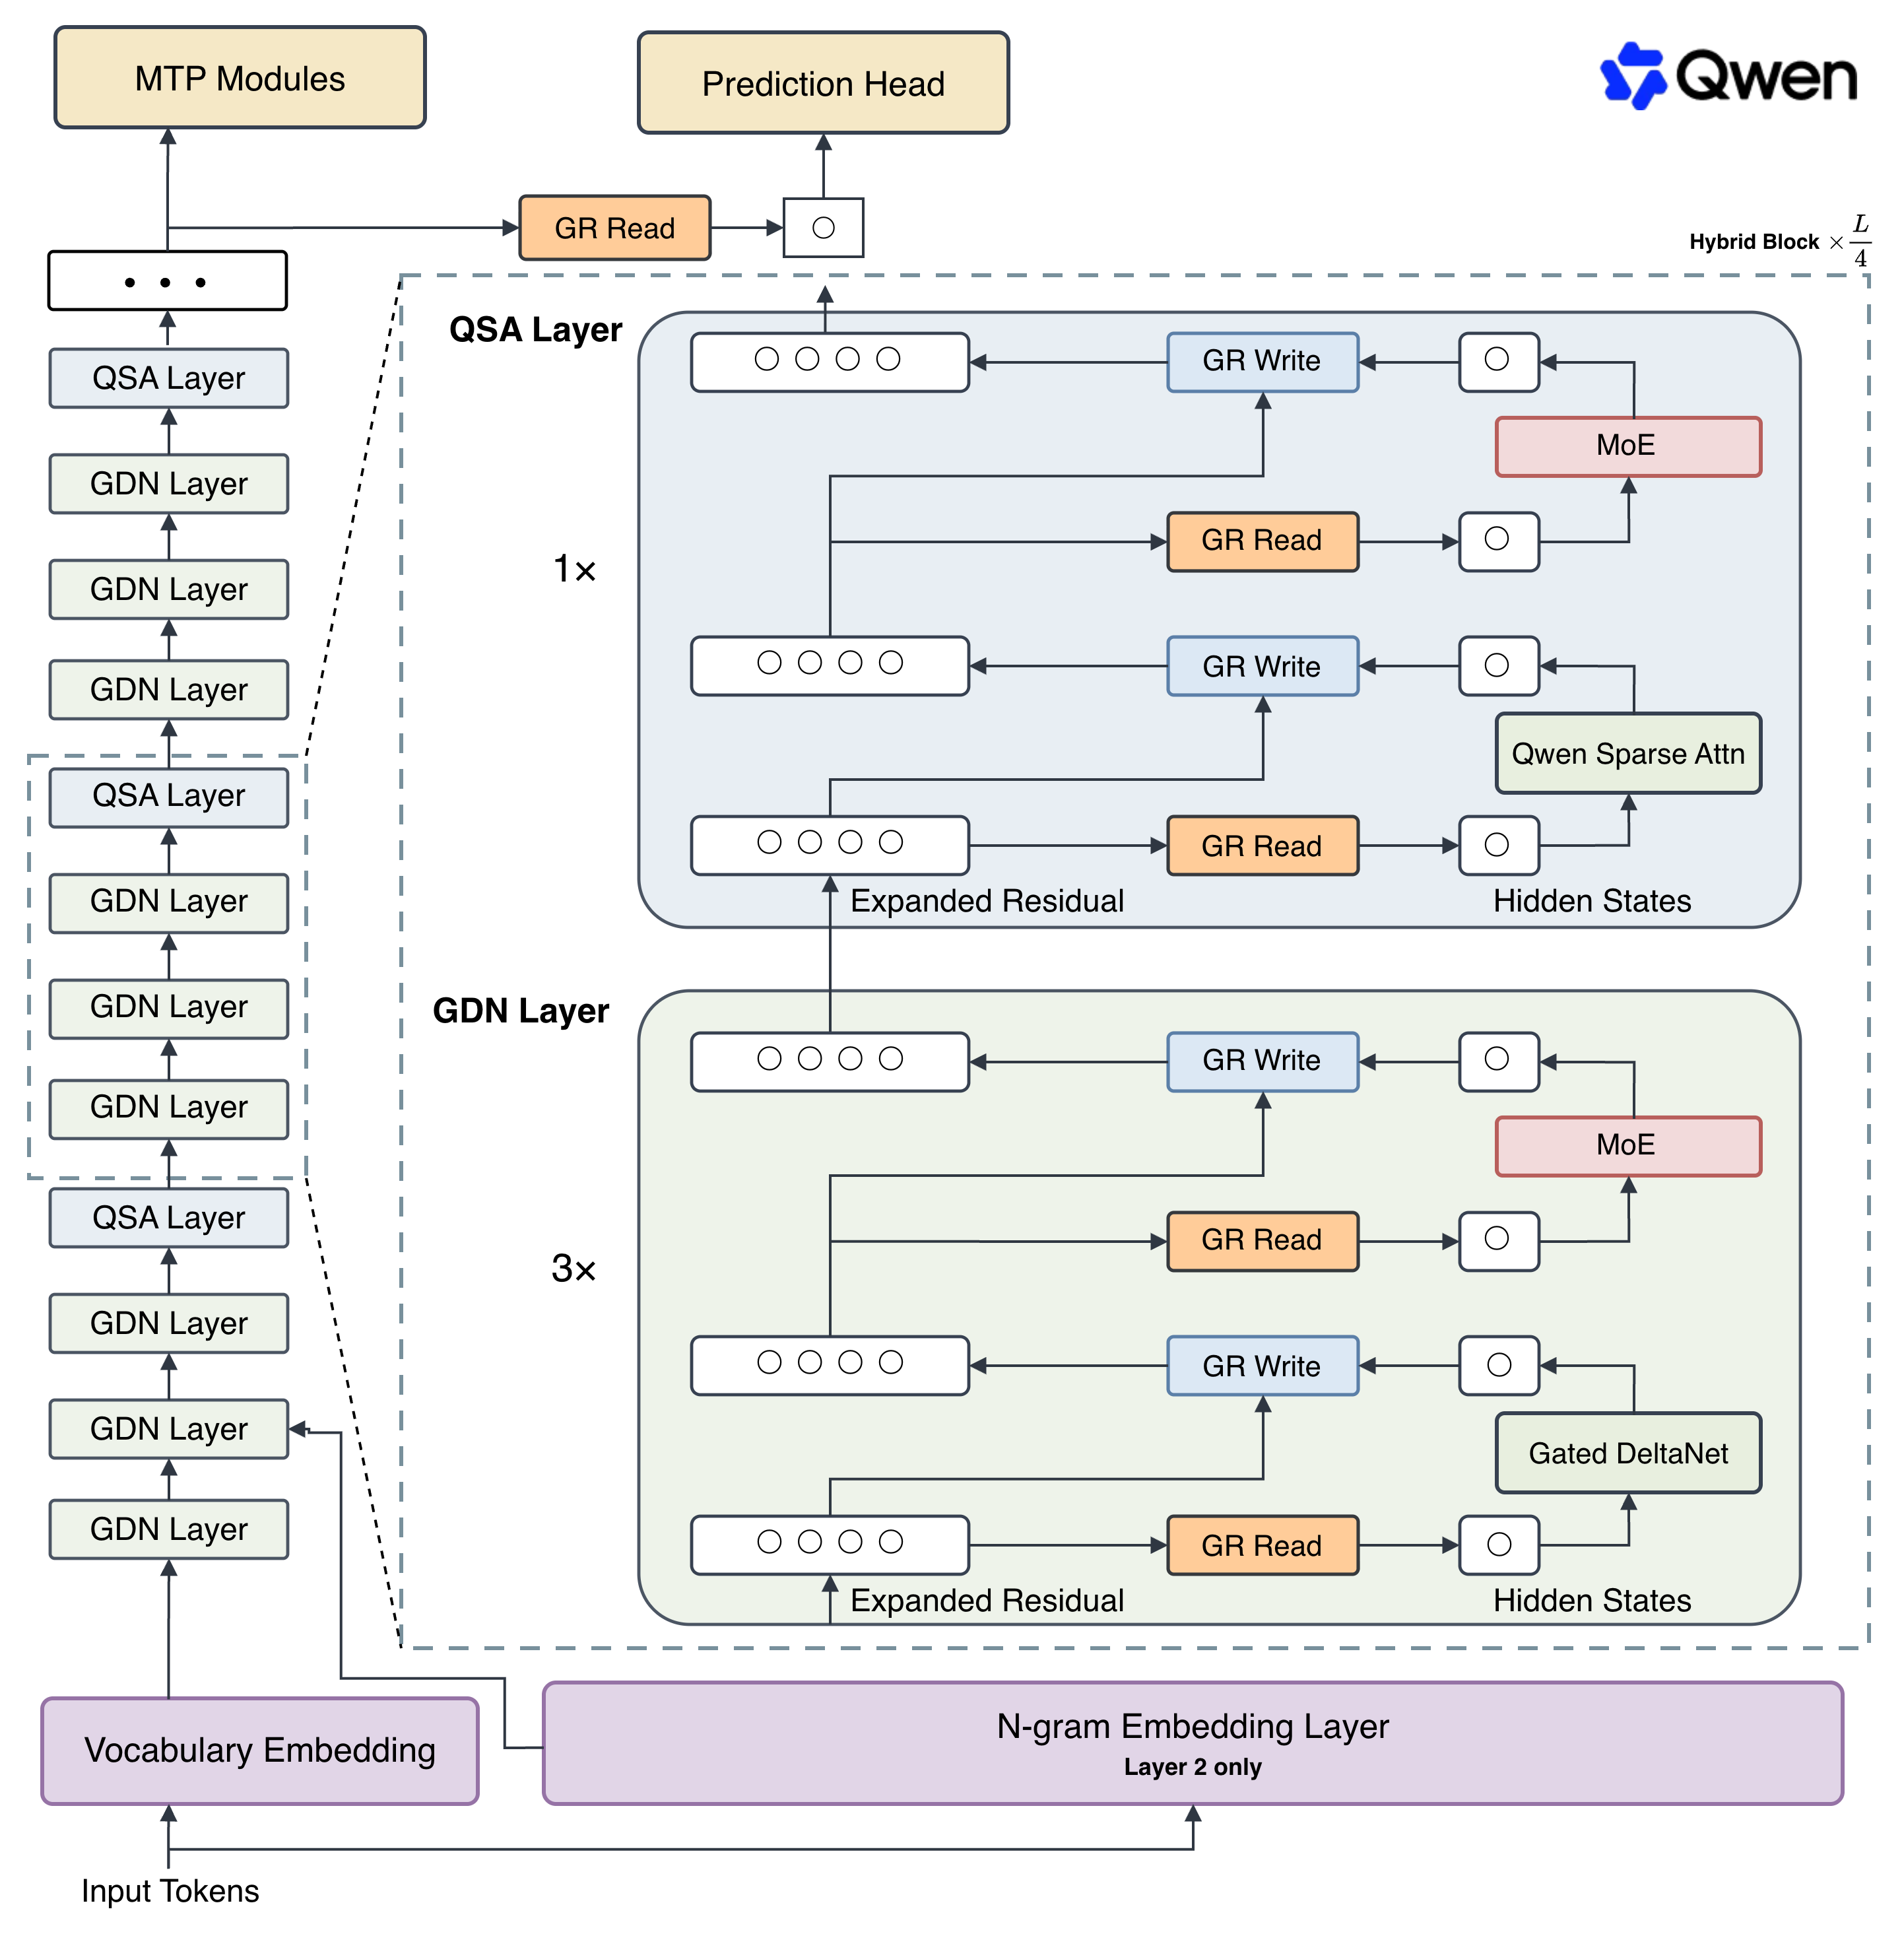
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0
glm-5.3
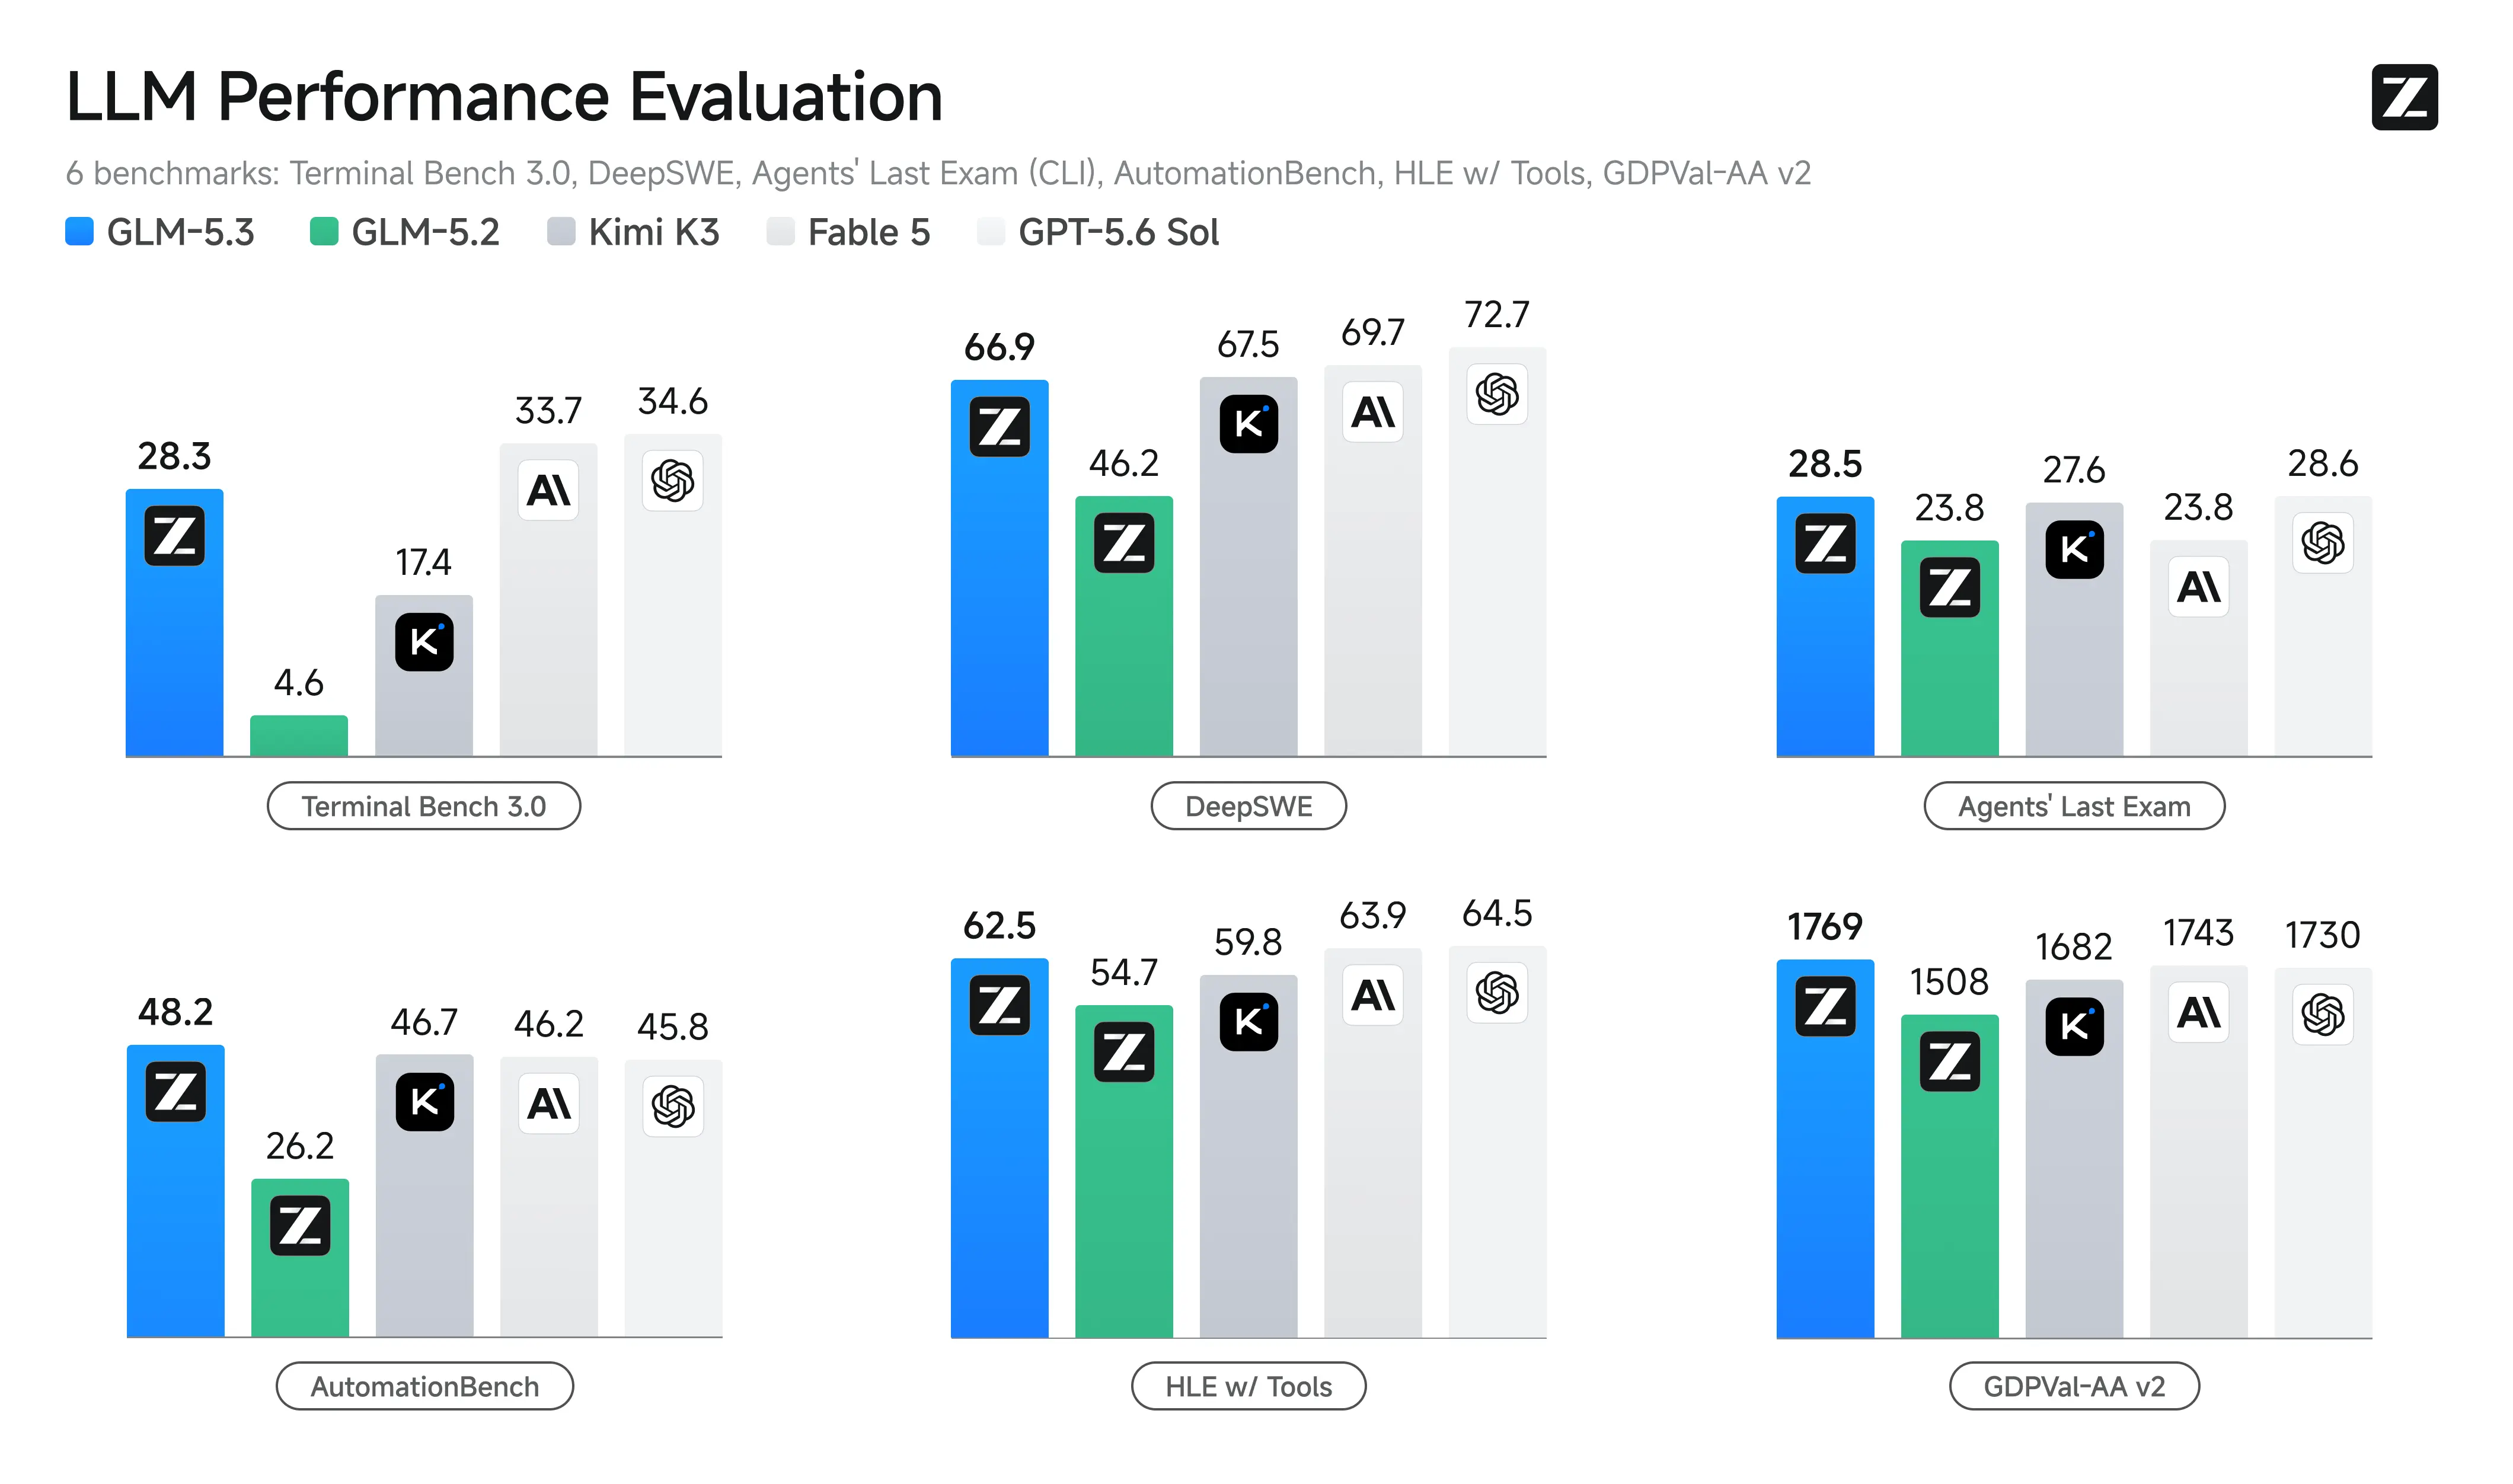
# GLM-5.3 GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks: + Stronger Coding: GLM-5.3 is the most capable open-weights model for coding, with a 50% improvement over GLM-5.2 on our in-house Z.ai Code Bench. It also achieve open-source SOTA on public benchmarks including Terminal Bench 3.0 and Agents' Last Exam. + Emergent Cyber Capability: As we scaled post-training, cyber capability developed faster than we expected. GLM-5.3 is state of the art on CyberGym for vulnerability discovery, and its gains are largest further up the exploitation chain, where it more than doubles GLM-5.2 on exploitation benchmarks. ## Benchmark ### Serve GLM-5.3 Locally GLM-5.3 supports deployment with the following frameworks. Feel free to try them out: - SGLang — see cookbook - vLLM — see recipes - TokenSpeed — see here - Transformers — see transformers docs - KTransformers — see tutorial - Unsloth — see guide - For deployment on the `Ascend NPU` platform, inference frameworks such as vLLM-Ascend, xLLM and SGLang are supported — see here. ### Note ...

Repository: localaiLicense: other

Attention: Trust Remote Code is required for this model
wemm-embedding-9b
WeMM-Embedding-9B is Tencent's largest Apache-2.0 multilingual embedding model built on Qwen3.5. This entry serves the original bfloat16 safetensors with LocalAI's Transformers backend and produces 4,096-dimensional normalized embeddings for text retrieval, semantic search, and RAG. The upstream model can also embed images and videos. LocalAI currently exposes text input through its embeddings API for this backend.

Repository: localaiLicense: apache-2.0

carbon-8b-q4
Carbon-8B is the largest model in Hugging Face's Carbon family of genomic foundation models. It targets DNA and RNA sequence generation, recovery, variant-effect prediction, and motif-perturbation analysis with a native context length of 32,768 hybrid 6-mer DNA tokens. This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 build is available as a variant. Prefix DNA sequences with `` and use uppercase A, C, G, and T characters in groups of six.

Repository: localaiLicense: apache-2.0

mxbai-embed-large-v1-q4
Mixedbread's mxbai-embed-large-v1 is a 335M-parameter English BERT embedding model for retrieval, semantic search, and RAG. It produces 1,024-dimensional embeddings and supports sequences up to 512 tokens. Prefix retrieval queries with `Represent this sentence for searching relevant passages: `. This entry uses the balanced Q4_K_M GGUF.

Repository: localaiLicense: apache-2.0
mxbai-embed-large-v1-q8
Mixedbread's mxbai-embed-large-v1 in the higher-fidelity Q8_0 GGUF format. This 335M-parameter English BERT model produces 1,024-dimensional embeddings for retrieval, semantic search, and RAG.

Repository: localaiLicense: apache-2.0

mxbai-embed-large-v1-f16
Mixedbread's mxbai-embed-large-v1 in the official full-precision F16 GGUF format. This 335M-parameter English BERT model produces 1,024-dimensional embeddings for retrieval, semantic search, and RAG.

Repository: localaiLicense: apache-2.0

nemotron-3-embed-8b-q4
Nemotron-3-Embed-8B is NVIDIA's larger multilingual text embedding model for retrieval, semantic search, and RAG. This Q4_K_M GGUF balances retrieval quality with local resource use and supports 36 languages. Prefix retrieval queries with `query: ` and documents with `passage: `.

Repository: localaiLicense: openmdw-1.1

qwen3.6-35b-a3b-genesis-hermes-v7-q8-k-p
Qwen3.6-35B-A3B Genesis Hermes V7 in the high-quality Q8_K_P GGUF format, with the shared F16 multimodal projector. This is the largest non-MTP build in the published V7 set.

Repository: localaiLicense: apache-2.0

ternary-bonsai-8b-q2-g64
Ternary Bonsai 8B (PrismML), GGUF Q2_0 with group-64 packing (each FP16 scale shared across 64 weights instead of 128). Slightly larger (~2.31 GB) but matches llama.cpp's native 64-value Q2_0 block layout. Runs on LocalAI's `bonsai` backend. License: Apache 2.0.

Repository: localaiLicense: apache-2.0

lfm2.5-1.2b-instruct
Try LFM • Docs • LEAP • Discord # LFM2.5-1.2B-Instruct LFM2.5 is a new family of hybrid models designed for **on-device deployment**. It builds on the LFM2 architecture with extended pre-training and reinforcement learning. - **Best-in-class performance**: A 1.2B model rivaling much larger models, bringing high-quality AI to your pocket. - **Fast edge inference**: 239 tok/s decode on AMD CPU, 82 tok/s on mobile NPU. Runs under 1GB of memory with day-one support for llama.cpp, MLX, and vLLM. - **Scaled training**: Extended pre-training from 10T to 28T tokens and large-scale multi-stage reinforcement learning. Find more information about LFM2.5 in our blog post. ## 🗒️ Model Details LFM2.5-1.2B-Instruct is a general-purpose text-only model with the following features: ...

Repository: localaiLicense: other

qwen3.6-27b-dflash
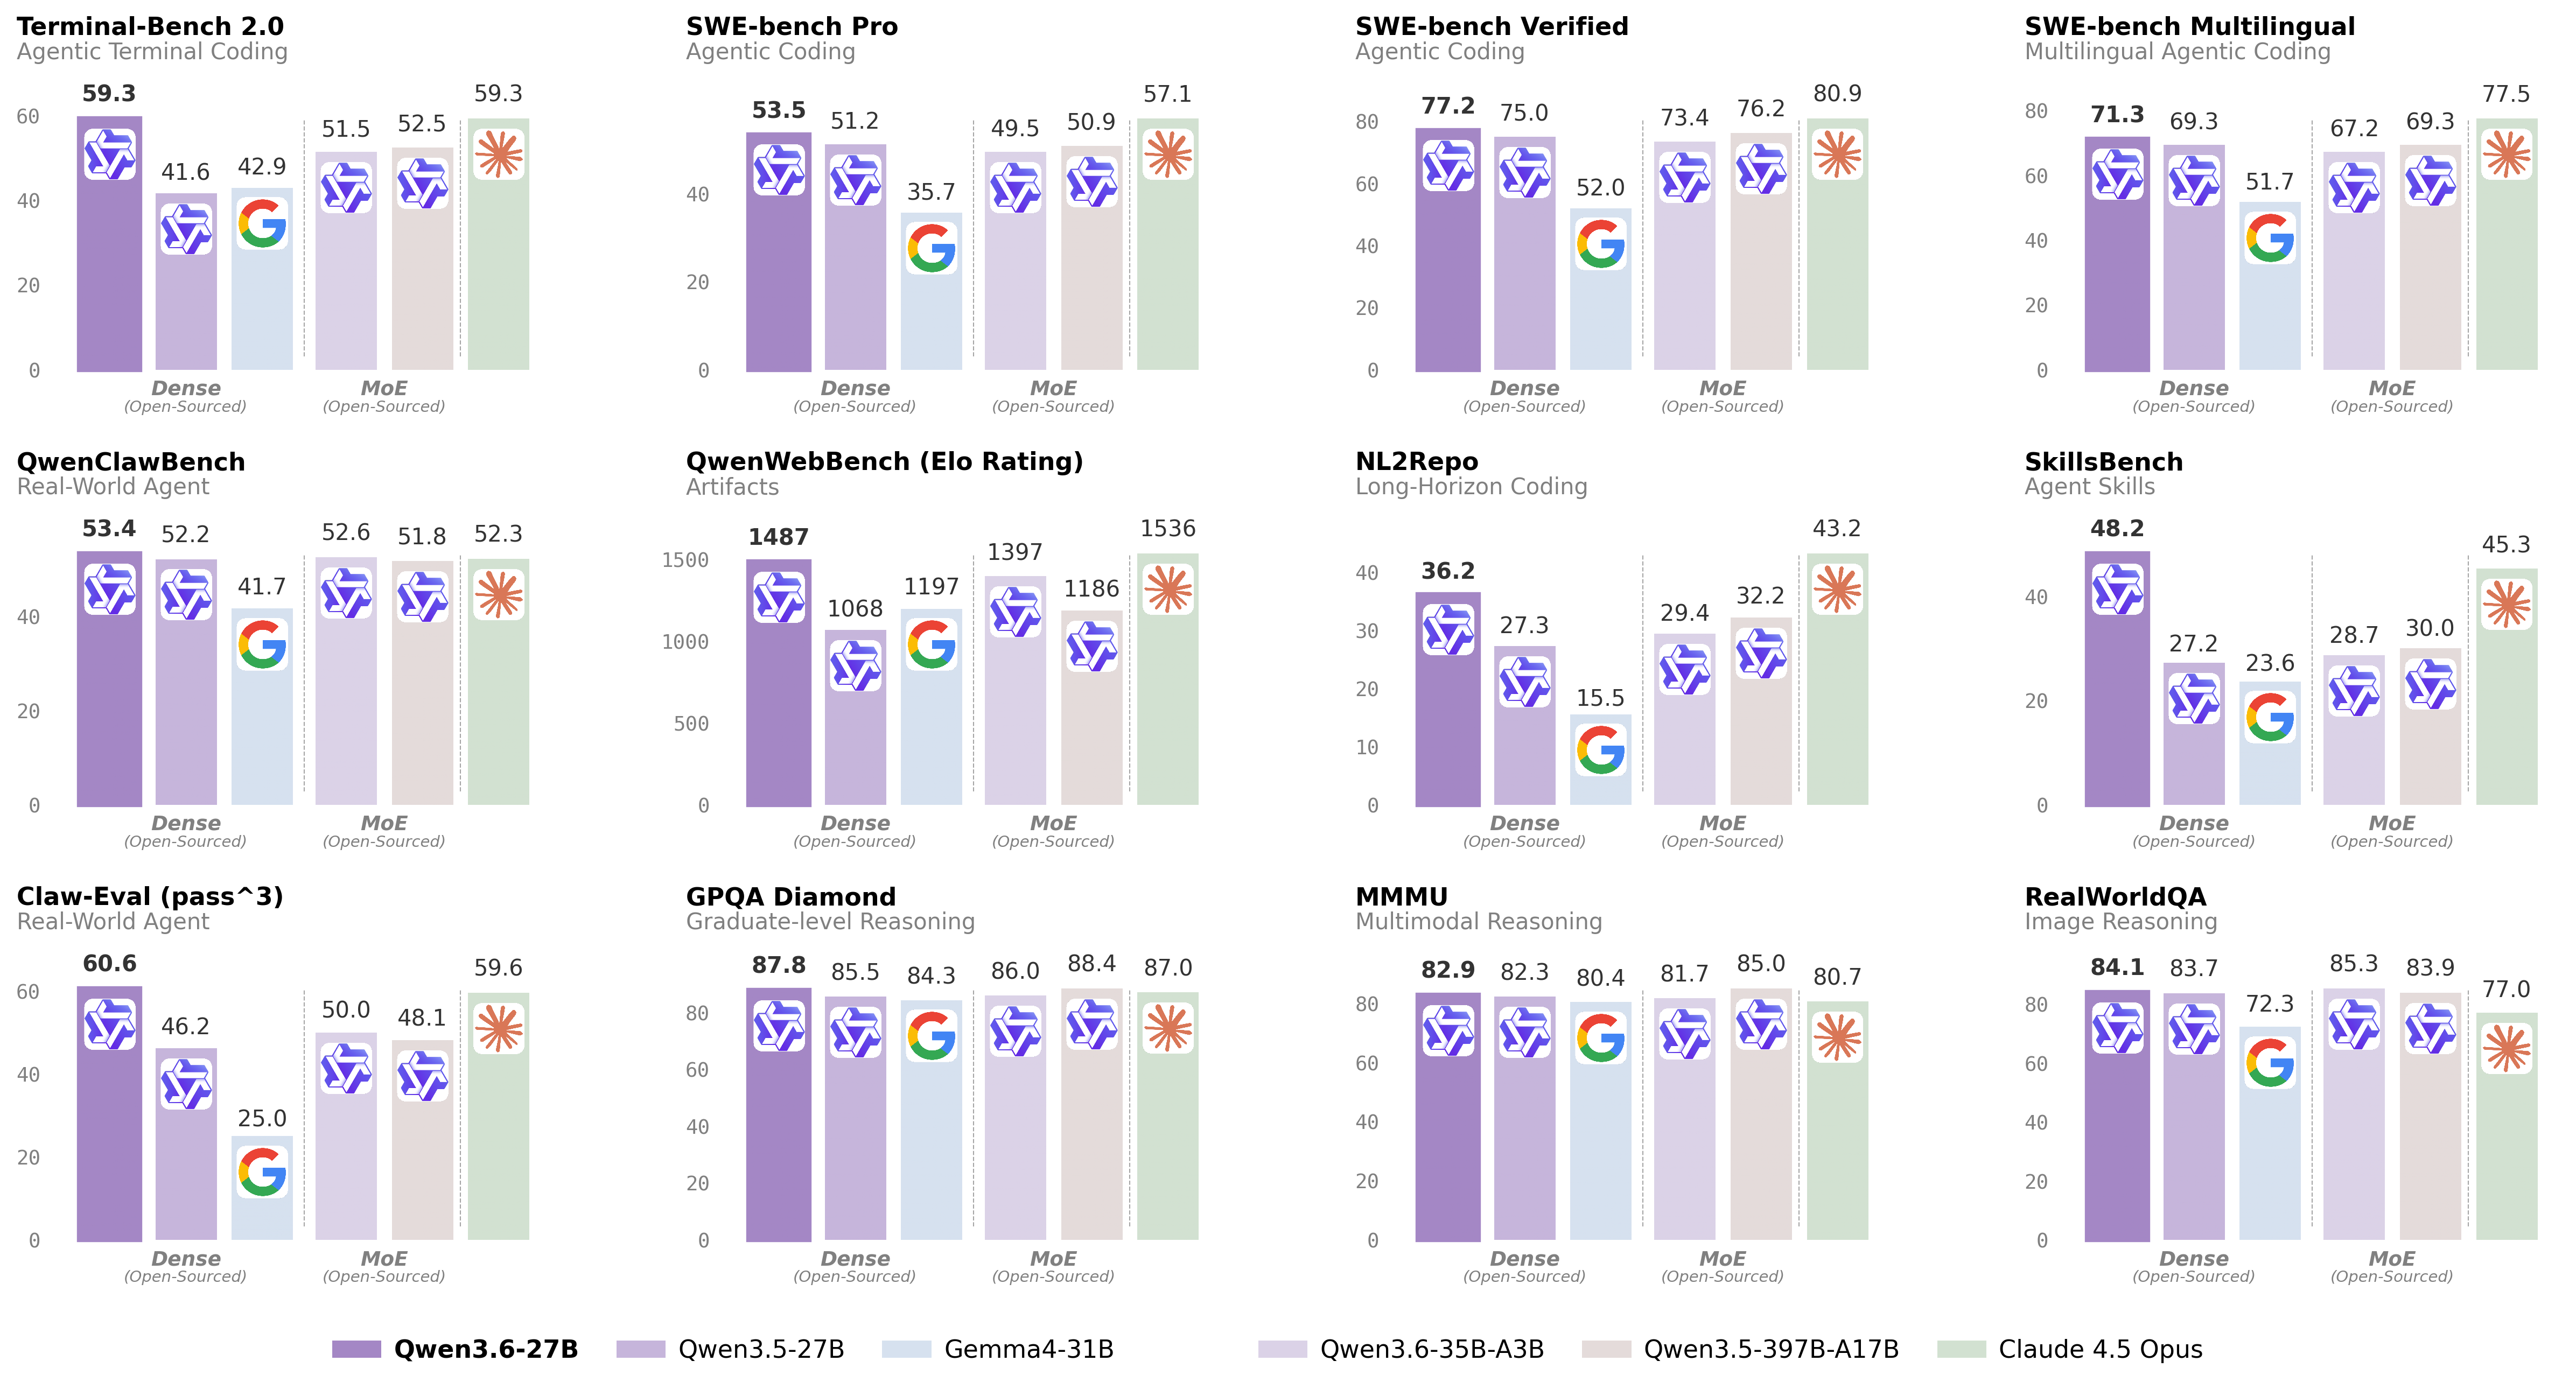
Qwen3.6-27B (dense) paired with its DFlash block-diffusion drafter for speculative decoding on the llama.cpp backend. DFlash gives its largest speedups on dense targets like this one. DFlash produces a whole block of draft tokens in a single forward pass and injects the target model's hidden states into the drafter's attention, which keeps the drafter tiny while making drafting GPU-friendly. The Q4_K_M file carries the full Qwen3.6-27B target; the ~1.8 GB Q8_0 drafter (`draft-dflash`) accelerates generation without changing the target's outputs. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here. Flash attention is required for DFlash and is enabled in this config. A GPU is recommended. License: Apache 2.0.

Repository: localaiLicense: apache-2.0

gemma-4-e2b-it-qat-q4_0
Gemma 4 E2B is a multimodal (text + image) instruction-tuned model from Google DeepMind, optimized with Quantization-Aware Training (QAT) to preserve bfloat16-level quality at a fraction of the memory. E2B is a MatFormer "effective 2B" elastic variant: it carries a larger backbone but runs at an effective 2B-parameter footprint, making it well suited to lightweight and on-device deployments. This is the official Google Q4_0 GGUF, shipped with its multimodal projector. License: Apache 2.0 | Authors: Google DeepMind

Repository: localaiLicense: apache-2.0

gemma-4-26b-a4b-it-qat-q4_0
Gemma 4 26B-A4B is a multimodal (text + image) instruction-tuned Mixture-of-Experts model from Google DeepMind, optimized with Quantization-Aware Training (QAT) to preserve bfloat16-level quality at a fraction of the memory. With 26B total parameters and ~4B active per token, it delivers large-model quality at a much lower inference cost. This is the official Google Q4_0 GGUF, shipped with its multimodal projector. License: Apache 2.0 | Authors: Google DeepMind

Repository: localaiLicense: apache-2.0

gemma-4-31b-it-qat-q4_0
Gemma 4 31B is the largest dense multimodal (text + image) instruction-tuned model in the Gemma 4 family from Google DeepMind, optimized with Quantization-Aware Training (QAT) to preserve bfloat16-level quality while dramatically reducing the memory required to load the model. This is the official Google Q4_0 GGUF, shipped with its multimodal projector. License: Apache 2.0 | Authors: Google DeepMind

Repository: localaiLicense: apache-2.0

gemma-4-31b-it-qat-mtp
Gemma 4 31B IT QAT (Google DeepMind), the largest dense model in the family, paired with its Multi-Token Prediction (MTP) drafter head for speculative decoding on the llama.cpp backend. The Q4_K_XL target carries the full multimodal (text + image) model; the small `mtp-gemma-4-31B-it` head predicts several tokens ahead which the target verifies in parallel, accelerating generation with no change to output quality. Dense models like 31B are the sizes that benefit most from MTP. The drafter is not a standalone chat model: it only runs paired with the target, which is why both are bundled here. It uses the upstream `gemma4-assistant` architecture registered by llama.cpp PR #23398, so it loads on stock llama.cpp without any patch. License: Apache 2.0 | Authors: Google DeepMind (target/drafter checkpoints), Unsloth (GGUF conversion)

Repository: localaiLicense: apache-2.0

Page 1 of many