Model Gallery

Discover and install AI models from our curated collection

46 models available
1 repositories
Documentation

Find Your Perfect Model

Filter by Model Type

Browse by Tags

qwen3.8-flash-next-ista-q2_0
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in ISTA-DASLab's 2-bit GSQ-RCO quantization (Q2_0), the fastest size (about 67 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 38 GB of RAM and VRAM together for the model (34 GB of experts in RAM plus about 10 GB for the system), and fast SSD storage: the 29 GB n-gram table stays on disk. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the GSQ-RCO quantization by ISTA-DASLab; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-ista-iq2_xs
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in ISTA-DASLab's 2-bit i-quant GSQ-RCO quantization (IQ2_XS), a little better than Q2_0 at close speed (about 69 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 39 GB of RAM and VRAM together for the model (35.5 GB of experts in RAM plus about 10 GB for the system), and fast SSD storage: the 29 GB n-gram table stays on disk. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the GSQ-RCO quantization by ISTA-DASLab; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-ista-iq3_xxs
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in ISTA-DASLab's 3-bit i-quant GSQ-RCO quantization (IQ3_XXS), better quality and slower (about 77 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 47 GB of RAM and VRAM together for the model (43 GB of experts in RAM plus about 10 GB for the system), and fast SSD storage: the 29 GB n-gram table stays on disk. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the GSQ-RCO quantization by ISTA-DASLab; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-ista-iq3_s
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in ISTA-DASLab's 3.5-bit i-quant GSQ-RCO quantization (IQ3_S), the best quality of the four, matching the full model on the published tests, and the slowest (about 85 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 55 GB of RAM and VRAM together for the model (50 GB of experts in RAM plus about 10 GB for the system; a 64 GB machine with little else running), and fast SSD storage: the 29 GB n-gram table stays on disk. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the GSQ-RCO quantization by ISTA-DASLab; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-coder-iq1_m
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in ISTA-DASLab's Coder release (IQ1_M): half of the experts (256 of 512 per layer) are kept, chosen on code, agent and image data, so it is smaller and faster but weaker outside code and in languages other than English (Chinese and other CJK text included) (about 59 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 32 GB of RAM (23 GB of experts in RAM) with a suitable GPU, and fast SSD storage: the 29 GB n-gram table stays on disk. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the Coder GSQ-RCO quantization by ISTA-DASLab; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

swift-1.5-qwen3.8-flash-next-iq2_xs
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in UkisAI's Swift 1.5 fine-tune, which thinks much shorter before it answers, at 2-bit i-quant (IQ2_XS) (about 69 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 39 GB of RAM and VRAM together for the model (the same as the same size of the original), and fast SSD storage for the n-gram table. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Two licences apply: UkisAI's Swift Open License 1.0 for the fine-tune, and the Qwen Community License 1.0 for the Qwen3.8-Flash-Next parts it is built from. Read both before you offer the model to other people. The GGUF files are the quantization by UkisAI of its Swift 1.5 fine-tune; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: swift-open-license-1.0

swift-1.5-qwen3.8-flash-next-iq3_xxs
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in UkisAI's Swift 1.5 fine-tune, which thinks much shorter before it answers, at 3-bit i-quant (IQ3_XXS) (about 77 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 47 GB of RAM and VRAM together for the model (the same as the same size of the original), and fast SSD storage for the n-gram table. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Two licences apply: UkisAI's Swift Open License 1.0 for the fine-tune, and the Qwen Community License 1.0 for the Qwen3.8-Flash-Next parts it is built from. Read both before you offer the model to other people. The GGUF files are the quantization by UkisAI of its Swift 1.5 fine-tune; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: swift-open-license-1.0

swift-1.5-qwen3.8-flash-next-iq3_s
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in UkisAI's Swift 1.5 fine-tune, which thinks much shorter before it answers, at 3.5-bit i-quant (IQ3_S) (about 85 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 55 GB of RAM and VRAM together for the model (the same as the same size of the original), and fast SSD storage for the n-gram table. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Two licences apply: UkisAI's Swift Open License 1.0 for the fine-tune, and the Qwen Community License 1.0 for the Qwen3.8-Flash-Next parts it is built from. Read both before you offer the model to other people. The GGUF files are the quantization by UkisAI of its Swift 1.5 fine-tune; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: swift-open-license-1.0

qwen3.8-flash-next-unsloth-ud-iq4_xs
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in Unsloth's Dynamic quantization (UD-IQ4_XS, about 4-bit i-quant) (about 95 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 72 GB of RAM to keep every expert in memory; with less, the mapped experts are read from the SSD while it answers, which works and is much slower. Keep the files on an SSD. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the Unsloth quantization; the vision projector is ISTA-DASLab's file for the original model; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-unsloth-ud-q4_k_xl
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in Unsloth's Dynamic quantization (UD-Q4_K_XL, 4-bit) (about 112 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 88 GB of RAM to keep every expert in memory; with less, the mapped experts are read from the SSD while it answers, which works and is much slower. Keep the files on an SSD. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the Unsloth quantization; the vision projector is ISTA-DASLab's file for the original model; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-unsloth-ud-q5_k_xl
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in Unsloth's Dynamic quantization (UD-Q5_K_XL, 5-bit, close to Q8_0) (about 159 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 108 GB of RAM to keep every expert in memory; with less, the mapped experts are read from the SSD while it answers, which works and is much slower. Keep the files on an SSD. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the Unsloth quantization; the vision projector is ISTA-DASLab's file for the original model; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-unsloth-ud-q6_k_xl
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in Unsloth's Dynamic quantization (UD-Q6_K_XL, 6-bit) (about 170 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 118 GB of RAM to keep every expert in memory; with less, the mapped experts are read from the SSD while it answers, which works and is much slower. Keep the files on an SSD. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the Unsloth quantization; the vision projector is ISTA-DASLab's file for the original model; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-unsloth-q8_0
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in Unsloth's Dynamic quantization (Q8_0, 8-bit, the reference quality) (about 189 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 136 GB of RAM to keep every expert in memory; with less, the mapped experts are read from the SSD while it answers, which works and is much slower. Keep the files on an SSD. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF files are the Unsloth quantization; the vision projector is ISTA-DASLab's file for the original model; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-gyro-s
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in agentionai's Gyro-S quantization (trellis-coded experts), the smallest option, for machines with little memory and lower in quality (about 59 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 28 GB of VRAM and RAM together for the weights. Half of the file is the n-gram table, which stays on disk and is read for every token, so keep it on a fast local SSD. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF file is the Gyro quantization by agentionai; the vision projector is ISTA-DASLab's file for the original model; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-gyro-m
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in agentionai's Gyro-M quantization (trellis-coded experts), about IQ3_XXS quality with about 20% less GPU memory, 16 to 21% slower than Q2_0 (about 93 GB to download). It reads images through the vision projector published for the original model, and the Strata backend parses its reasoning and tool calls. Needs about 35 GB of VRAM and RAM together for the weights. Half of the file is the n-gram table, which stays on disk and is read for every token, so keep it on a fast local SSD. Needs a GPU the strata backend supports; NVIDIA with 12 GB of VRAM or more is the class Strata tests. Runs only on the experimental strata backend. On the first load the strata backend builds the Strata pack from the GGUF files (a few minutes, a few GB of extra disk); a finished pack is never rebuilt. The experts are read from the GGUF files in place (mapped); add --resident-experts to engine_args to copy them into RAM when there is room. Licensed under the Qwen Community License 1.0 (inherited from Qwen/Qwen3.8-Flash-Next): free use, but a Model as a Service or AI Work Assistant business needs a licence from Qwen. Read the LICENSE file in the repository first. The GGUF file is the Gyro quantization by agentionai; the vision projector is ISTA-DASLab's file for the original model; Strata is by Niko1221. The MTP draft layer is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-nvfp4-gptq
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, with every routed expert quantized to NVFP4 by GPTQ and packed for the Strata inference engine (a Strata pack plus GGUF side files, about 129 GB to download). It reads images through the vision projector published by ISTA-DASLab for the original model, and the Strata backend parses its reasoning and tool calls. Needs an NVIDIA GPU with 12 GB of VRAM or more (RTX 20 series or newer, or a DGX Spark) and about 80 GB of RAM (about 69 GiB of expert weights are kept in memory), plus fast SSD storage for the 48 GiB n-gram table. Runs only on the NVIDIA builds of the experimental strata backend. The weights are the Strata NVFP4 conversion by Maximilian228 of Qwen/Qwen3.8-Flash-Next, licensed under the Qwen Community License 1.0. The MTP draft layer shipped in the repository is not configured here.

Repository: localaiLicense: qwen-community-1.0

qwen3.8-flash-next-nvfp4-nvidia
Qwen3.8-Flash-Next, a 125B-parameter hybrid mixture-of-experts model, in NVIDIA's NVFP4 quantization (nvidia/Qwen3.8-Flash-Next-NVFP4), converted to a Strata pack with GGUF side files (about 129 GB to download). It reads images through the vision projector published by ISTA-DASLab for the original model, and the Strata backend parses its reasoning and tool calls. Needs an NVIDIA GPU with 12 GB of VRAM or more (RTX 20 series or newer, or a DGX Spark) and about 80 GB of RAM (about 69 GiB of expert weights are kept in memory), plus fast SSD storage for the 48 GiB n-gram table. Runs only on the NVIDIA builds of the experimental strata backend. Two licences apply: the NVIDIA Open Model License Agreement (NVIDIA's quantization) and the Qwen Community License 1.0 (the base model). The conversion to the Strata format is by Maximilian228. The MTP draft layer shipped in the repository is not configured here.

Repository: localaiLicense: nvidia-open-model-license
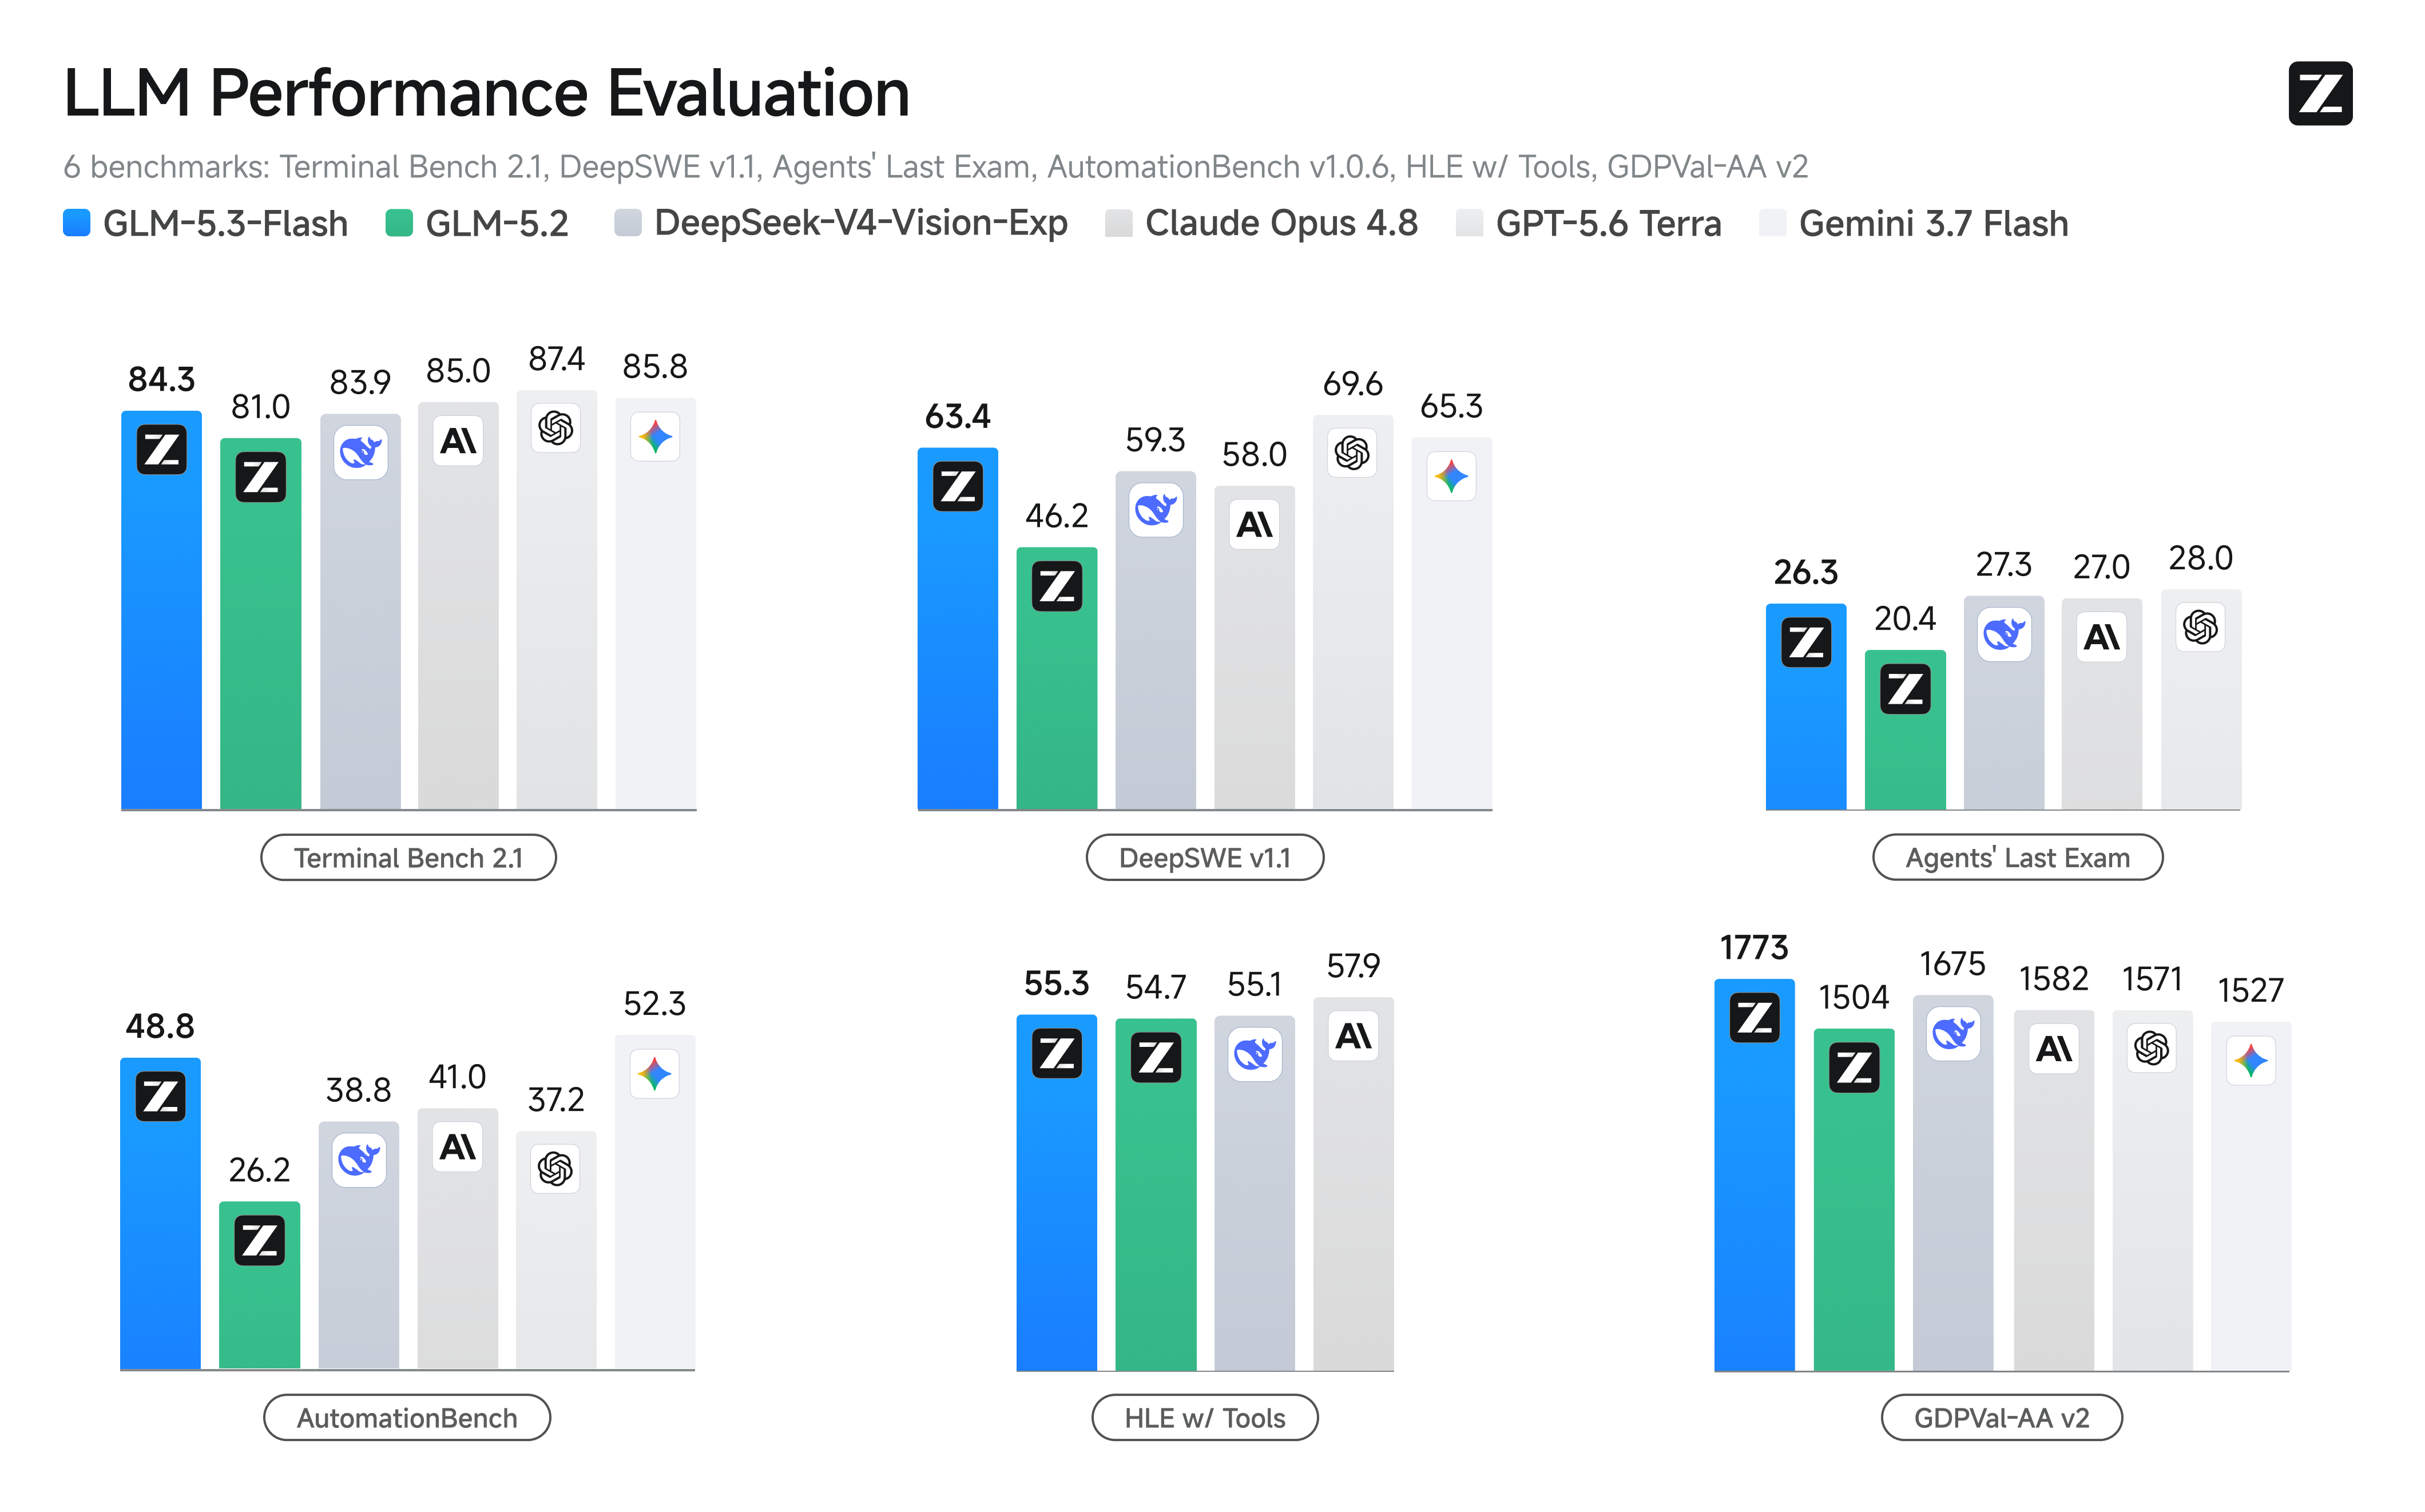
glm-5.3-flash
# GLM-5.3-Flash 👋 Join our WeChat or Discord community. 📖 Check out the GLM-5.3-Flash blog and GLM-5 Technical report. 📍 Use GLM-5.3-Flash API services on Z.ai API Platform. ## Introduction We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it outperforms GLM-5.2 across benchmarks and real-world workloads at one-tenth the price, while approaching Claude Opus 4.8 on coding and agentic benchmarks. GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. For the first time in the GLM series, we introduce a hybrid architecture combining sparse and linear attention, sharply reducing long-context serving costs while preserving precise long-context capabilities. The model also adopts Manifold-Constrained Hyper-Connections (mHC) to further improve scaling efficiency. Together with our latest 30T-token multimodal pre-training corpus, these changes enable GLM-5.3-Flash to deliver more intelligence with less compute. ## Serve GLM-5.3-Flash Locally ...

Repository: localaiLicense: mit

ling-3.0-tiny-q4
Ling-3.0-tiny is InclusionAI's MIT-licensed hybrid reasoning MoE model with 7.9B total parameters and 1.3B active parameters per token. It targets reasoning, coding, instruction following, and agentic tasks with a native 131K-token context window. This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 model is available as a variant.

Repository: localaiLicense: mit

ling-3.0-flash-iq1
Ling-3.0-flash is InclusionAI's MIT-licensed hybrid reasoning MoE model with 124B total parameters and 5.5B active parameters per token. It targets coding, deep research, instruction following, and agentic workflows with a native 256K-token context window. This default entry uses the 36.5 GB AD-IQ1_M GGUF. A higher-quality 44.7 GB AD-IQ2_XS model is available as a variant.

Repository: localaiLicense: mit

carbon-3b-q4
Carbon-3B is Hugging Face's 3B-parameter genomic foundation model for DNA and RNA sequence generation, recovery, variant-effect prediction, and motif-perturbation analysis. It supports 32,768 tokens natively and uses a hybrid tokenizer with 6-mer DNA tokens. This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 build is available as a variant. Prefix DNA sequences with `` and use uppercase A, C, G, and T characters in groups of six.

Repository: localaiLicense: apache-2.0

Page 1 of many