Model Gallery

Discover and install AI models from our curated collection

505 models available
1 repositories
Documentation

Find Your Perfect Model

Filter by Model Type

Browse by Tags

deepseek-v4.1-flash-ista-coder-iq2_xxs
ISTA-DAS's coding version of DeepSeek-V4.1-Flash-1017: in every layer 192 of the 384 routed experts are kept and the other 192 removed, stored in the 2.00 bpw (IQ2_XXS) layout. It is the smallest DeepSeek-V4.1 set here (about 191 GB to download). It writes a reasoning trace before the answer, and the Strata backend splits it from the reply and parses the model's DSML tool calls. Text only: images are not supported by this backend. Needs a GPU with 12 GB of VRAM or more and about 24 GB of RAM at the least (Strata's figure; its measurements use 46 to 64 GB: an RTX 5070 with 64 GB answered at about 5 tokens per second, an RTX 3060 with 46 GB at 8 to 10). Less RAM still runs, slowly. Strata measured a perplexity 48% above the original model on its test set (KL 0.40), so it is weaker than the full sets on prose and general knowledge; it is meant for code and agent work. Needs about 192 GB of free disk, on a fast NVMe drive: the 111 GB n-gram table (Engram) stays on disk and is read for every token. The Engram table and the 8 GB DSpark draft model are shared by all DeepSeek-V4.1 entries and downloaded once into strata/models/deepseek-v4.1-flash-shared. Runs only on the experimental strata backend, on NVIDIA CUDA 13 (x86_64 and arm64), AMD Radeon RX 9070 and R9700 (ROCm) and Apple Silicon (Metal). Strata ships no DeepSeek engine for CUDA 12, Intel or other AMD cards. On the first load the strata backend builds the Strata pack from the GGUF files (under a minute, a few MB of extra disk); loading the model afterwards takes a few minutes. The default context is 8192 tokens, the size Strata checked; raise context_size if the GPU has room. Licensed under the MIT License (DeepSeek-V4.1-Flash-1017 and the quantized files). The GGUF files are the GSQ-RCO quantization by ISTA-DAS (ISTA-DASLab); the DSpark draft model is Unsloth's; Strata is by Niko1221.

Repository: localaiLicense: mit

qwen3.5-4b-3d-coder-q8
CCORE's early preview fine-tune of Qwen3.5-4B for coding and Three.js scene generation. This text-only Q8_0 build pins a preview checkpoint and uses the embedded chat template. MTP is not enabled.

Repository: localaiLicense: apache-2.0
qwen3.8-27b-defiance-iq4
Defiance combines HauhauCS's uncensored Qwen3.8-27B weights with a customized Turbo Brilliance chat template for reasoning and roleplay. This IQ4_XS GGUF build uses llama.cpp and the embedded template, with a 32,768-token context. Text input only; MTP is not enabled.

Repository: localaiLicense: apache-2.0
qwen3.8-27b-defiance-q6
Defiance combines HauhauCS's uncensored Qwen3.8-27B weights with a customized Turbo Brilliance chat template for reasoning and roleplay. This Q6_K_P GGUF build uses llama.cpp and the embedded template, with a 32,768-token context. Text input only; MTP is not enabled.

Repository: localaiLicense: apache-2.0

humanizer-12b-bf16
Humanizer is a 12B Gemma 4 fine-tune for rewriting English and Chinese text. This unquantized BF16 GGUF build uses llama.cpp with an 8,192-token context. This entry uses the completions API with the publisher's exact rewriting prompt.

Repository: localaiLicense: apache-2.0

spark-x2.5-4b
# Spark-X2.5 [](https://join.slack.com/t/tokenspark/shared_invite/zt-432qf8l2f-5~dLyXv8uETr0P0UuC07nw) [](https://discord.gg/kTDE2Hg8aw) [](https://www.youtube.com/@SparkLLM) [](https://dev.to/sparkllm) [](https://bsky.app/profile/sparkllm.bsky.social) [](https://x.com/sparkllm) [](https://www.zhihu.com/people/zhiikz7qh7m) [](images/xhtoken-wechat.jpg) > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. ## Introduction We are introducing Spark-X2.5-4B and Spark-X2.5-1.7B, two compact, general-purpose language models designed to make capable AI more practical, efficient, and accessible. The models deliver strong performance across a broad range of everyday tasks—including conversation, writing, translation, reasoning, coding, tool use, and agentic workflows—achieving leading results among open-source models of comparable size. Spark-X2.5 combines an efficiency-oriented architecture with native context windows of up to 1M tokens, and support for more than 200 languages. ...

Repository: localaiLicense: apache-2.0

qwen3.8-flash-next-uncensored
# Qwen3.8-Flash-Next > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > > In particular, **Qwen3.8-Flash** is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-Flash Overview. As the frontier of foundation models pushes toward ever-larger parameter counts and ever-longer context windows, the question is no longer just how much we can scale, but how efficiently we can do so. Sustainable progress toward artificial general intelligence (AGI) that benefits everyone demands architectural innovation. Today, we are sharing a concrete step in that direction: Qwen3.8-Flash-Next. ...

Repository: localaiLicense: apache-2.0

deepseek-v4-flash-vision-exp
# DeepSeek-V4-Flash-Vision-Exp ## Introduction We are excited to introduce **DeepSeek-V4-Flash-Vision-Exp**, our first experimental multimodal model in the DeepSeek-V4 family. It builds on the DeepSeek-V4-Flash architecture by incorporating visual modules and undergoing continued training to unlock visual understanding capabilities. Compared to DeepSeek-V4-Flash-0731, DeepSeek-V4-Flash-Vision-Exp achieves substantial improvements on its multimodal agent capabilities, while maintaining comparable performance on text-only agent tasks. Notes: 1. For the text agent benchmarks above, DeepSeek models are evaluated with the minimal mode of DeepSeek Harness as the agent framework, using the `max` reasoning effort level with `temperature = 1.0, top_p = 0.95`. 2. † For ApexBench and Agents' Last Exam, DeepSeek-V4-Flash-0731 ignores the multimodal elements in the input. ## Repository layout This repository contains the tokenizer, prompt encoding reference, and a minimal PyTorch inference implementation for DeepSeek-V4 Flash Vision. The reference inference covers the vision encoder and aligner, DFlash attention, MoE, Hyper-Connections, and the DSpark forward path. ...

Repository: localaiLicense: mit

hemmingway-1
Hemmingway-1 is Altworld's English-first 27B text model, fine-tuned from Qwen3.8-27B for everyday messages and creative writing. This Q4_K_M GGUF build uses llama.cpp and the model's embedded chat template. Licensed under CC BY-NC 4.0; commercial use requires a separate agreement.

Repository: localaiLicense: cc-by-nc-4.0
hemmingway-1-q8
Hemmingway-1 is Altworld's English-first 27B text model, fine-tuned from Qwen3.8-27B for everyday messages and creative writing. This Q8_0 GGUF build uses llama.cpp and the model's embedded chat template. Licensed under CC BY-NC 4.0; commercial use requires a separate agreement.

Repository: localaiLicense: cc-by-nc-4.0

qwen3.8-27b
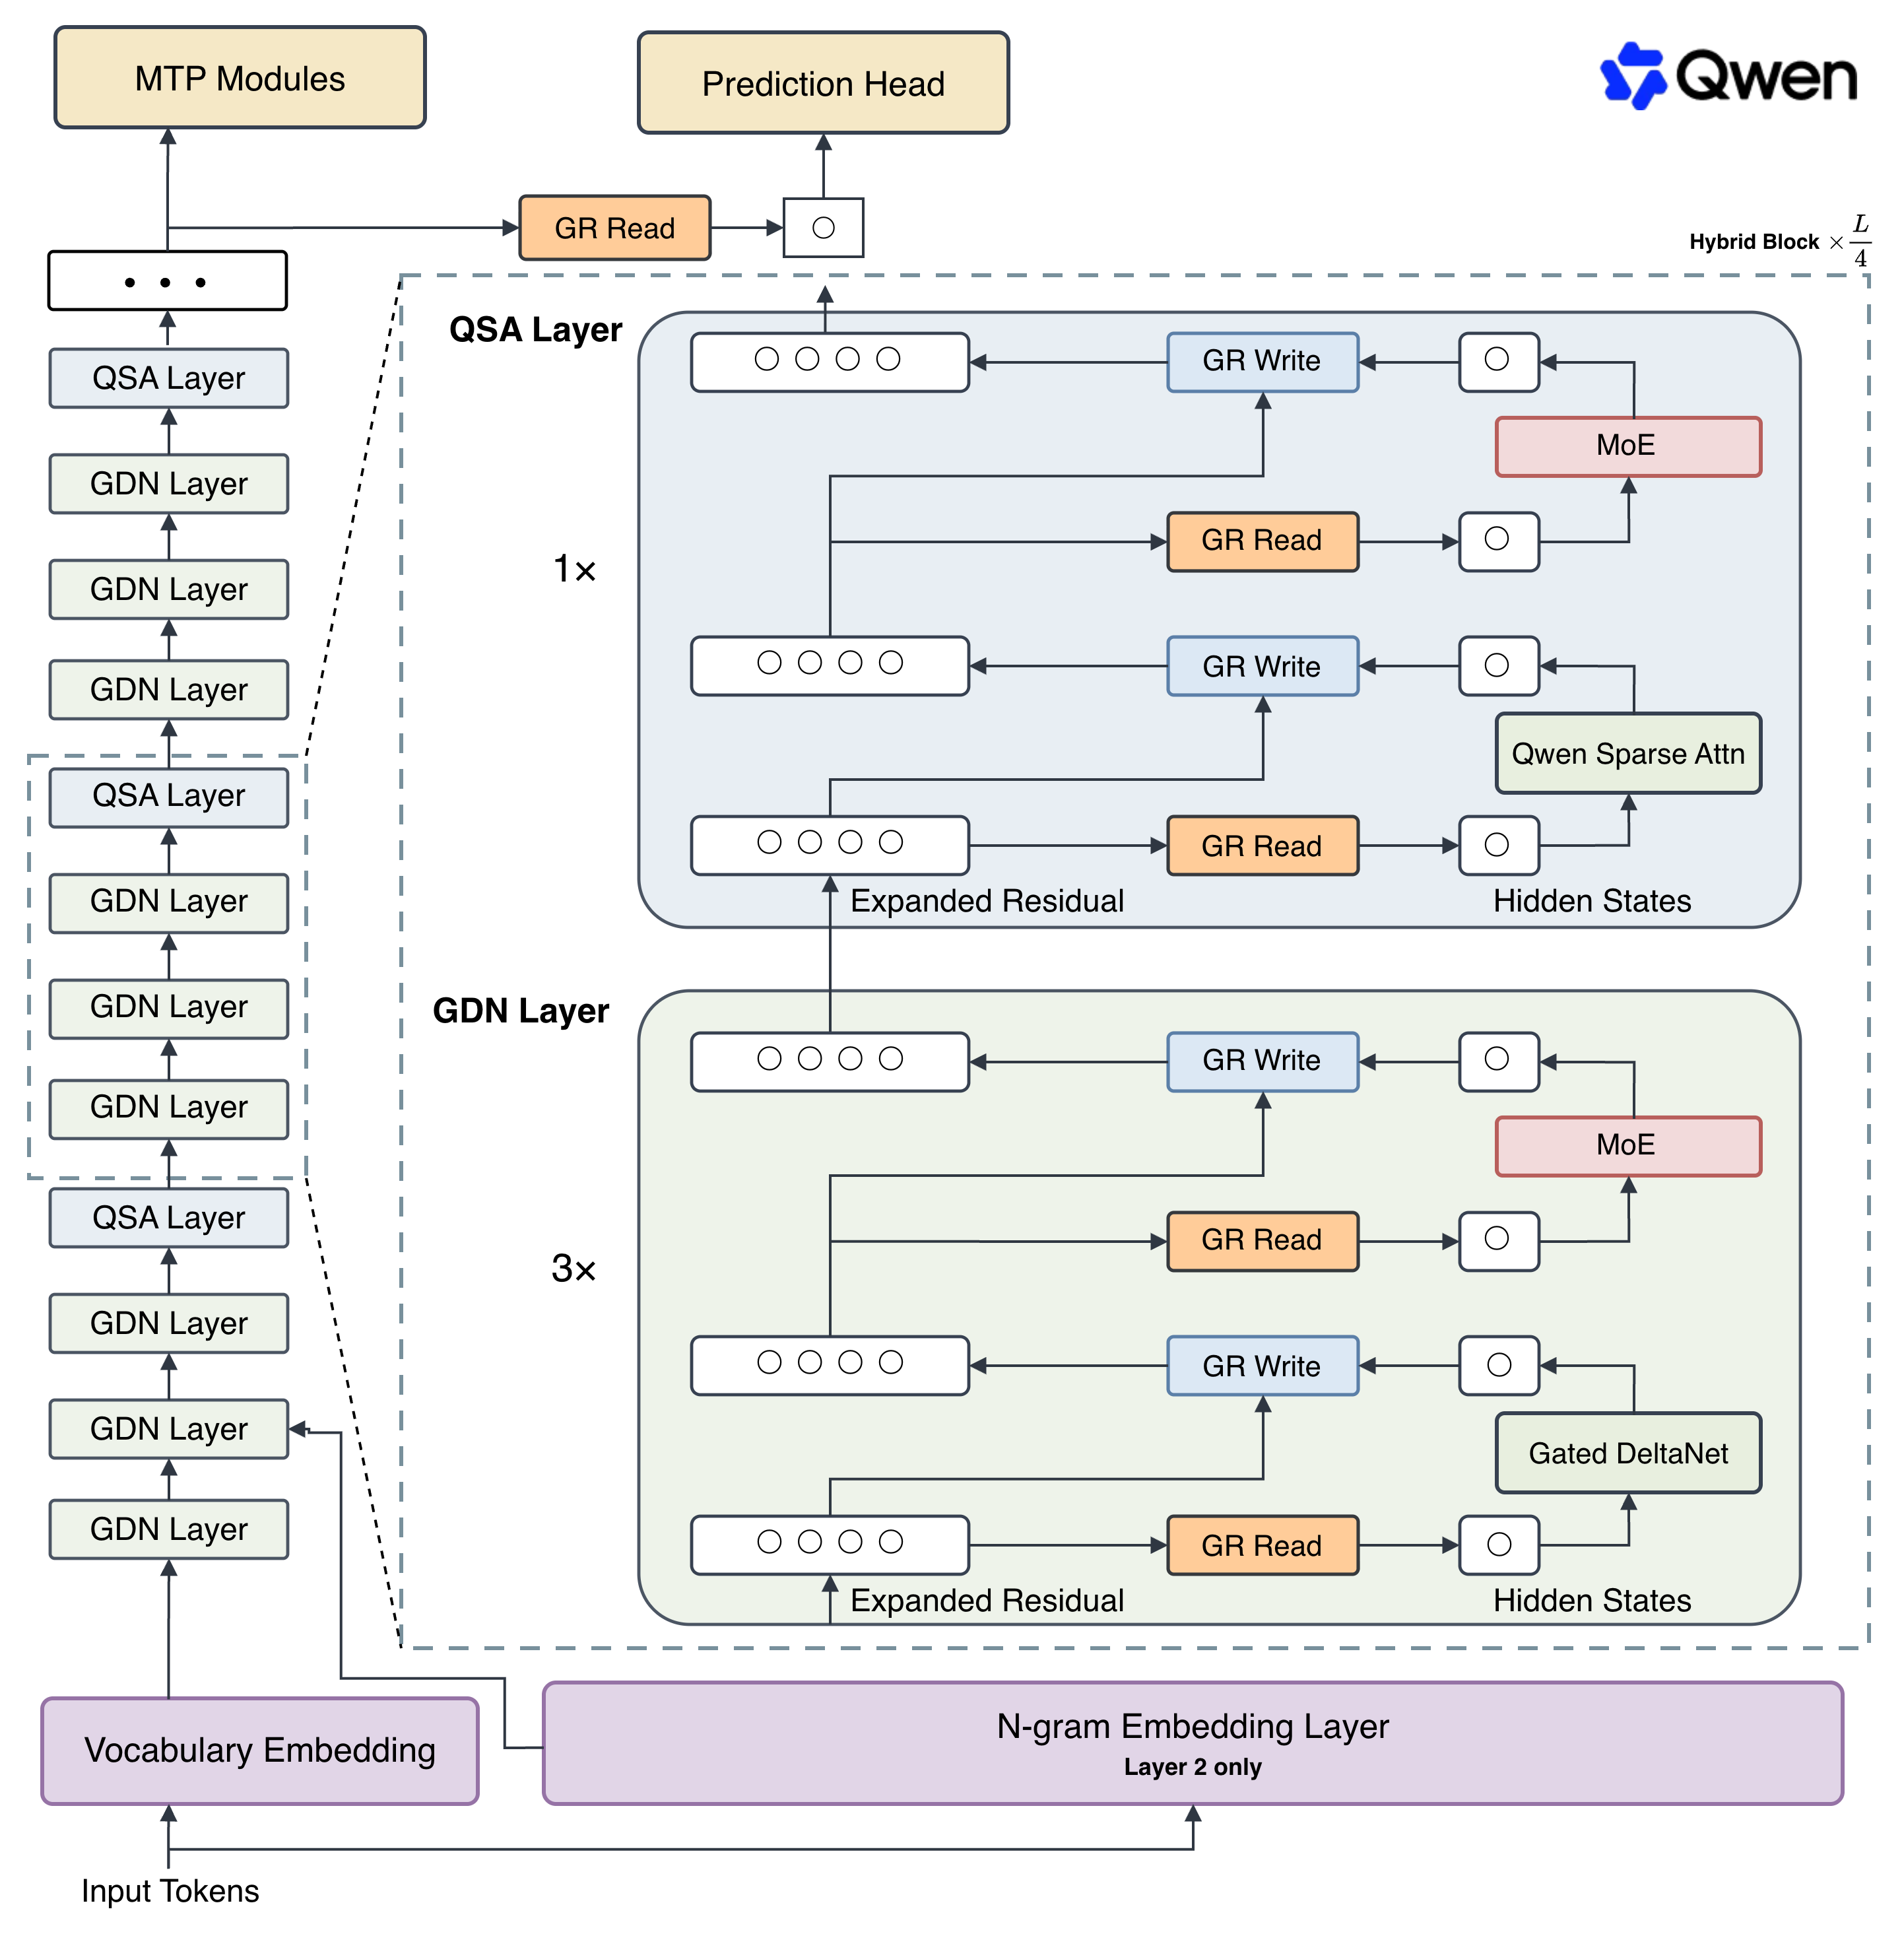
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0
qwen3.8-27b-uncensored-hauhaucs-aggressive-mtp
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-uncensored
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-turbo-fable-cold-fusion-735-882-heretic-uncensored-neo-coder-max-mtp
RELEASE #1 GGUFS [including detailed notes, how to use, benches and much more]: https://huggingface.co/DavidAU/Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NEO-CODER-MAX-MTP-GGUF Qwen3.8-27B-TURBO-Fable-Cold-Fusion-735-882-Heretic-Uncensored-NM-DAU (release #1, others pending...) ( repo has 10+ other versions (and 3 branches) noted below that EXCEED the performance of all QWEN 27B models, including fine tunes. ) First, special thanks to Nightmedia for working on the first three stages prior to heretic'ing/post staging and benching everything (3 sections below). A number of my finetunes - both released and non-released - were used here as well as some third parties. Full details will be disclosed upon final release as the project shores up. THREE example generations [snippets] from STAGE1-PART2, STAGE1b-PART2 and STAGE2-rplus2 at the bottom of the page. Release(s) will be GGUFS first (linked here directly) then source code shortly thereafter [now released/open]. Some additional work and/ spawning of new branches from branch(es) below is still going on. NEW: Branch 3 added, see below. COMPLETED AND PENDING RELEASES: ...

Repository: localaiLicense: apache-2.0

nl2sh-1.5b-q4
nl2sh-1.5b is a 1.5B Qwen2.5-Coder fine-tune that converts plain-English requests into single POSIX or Bash commands. This Q4_K_M GGUF is 941 MB and is designed for fast CPU inference. Use the system prompt from the model card and review every generated command before execution. The model can produce destructive commands and cannot inspect the local filesystem.

Repository: localaiLicense: apache-2.0

glm-5.3
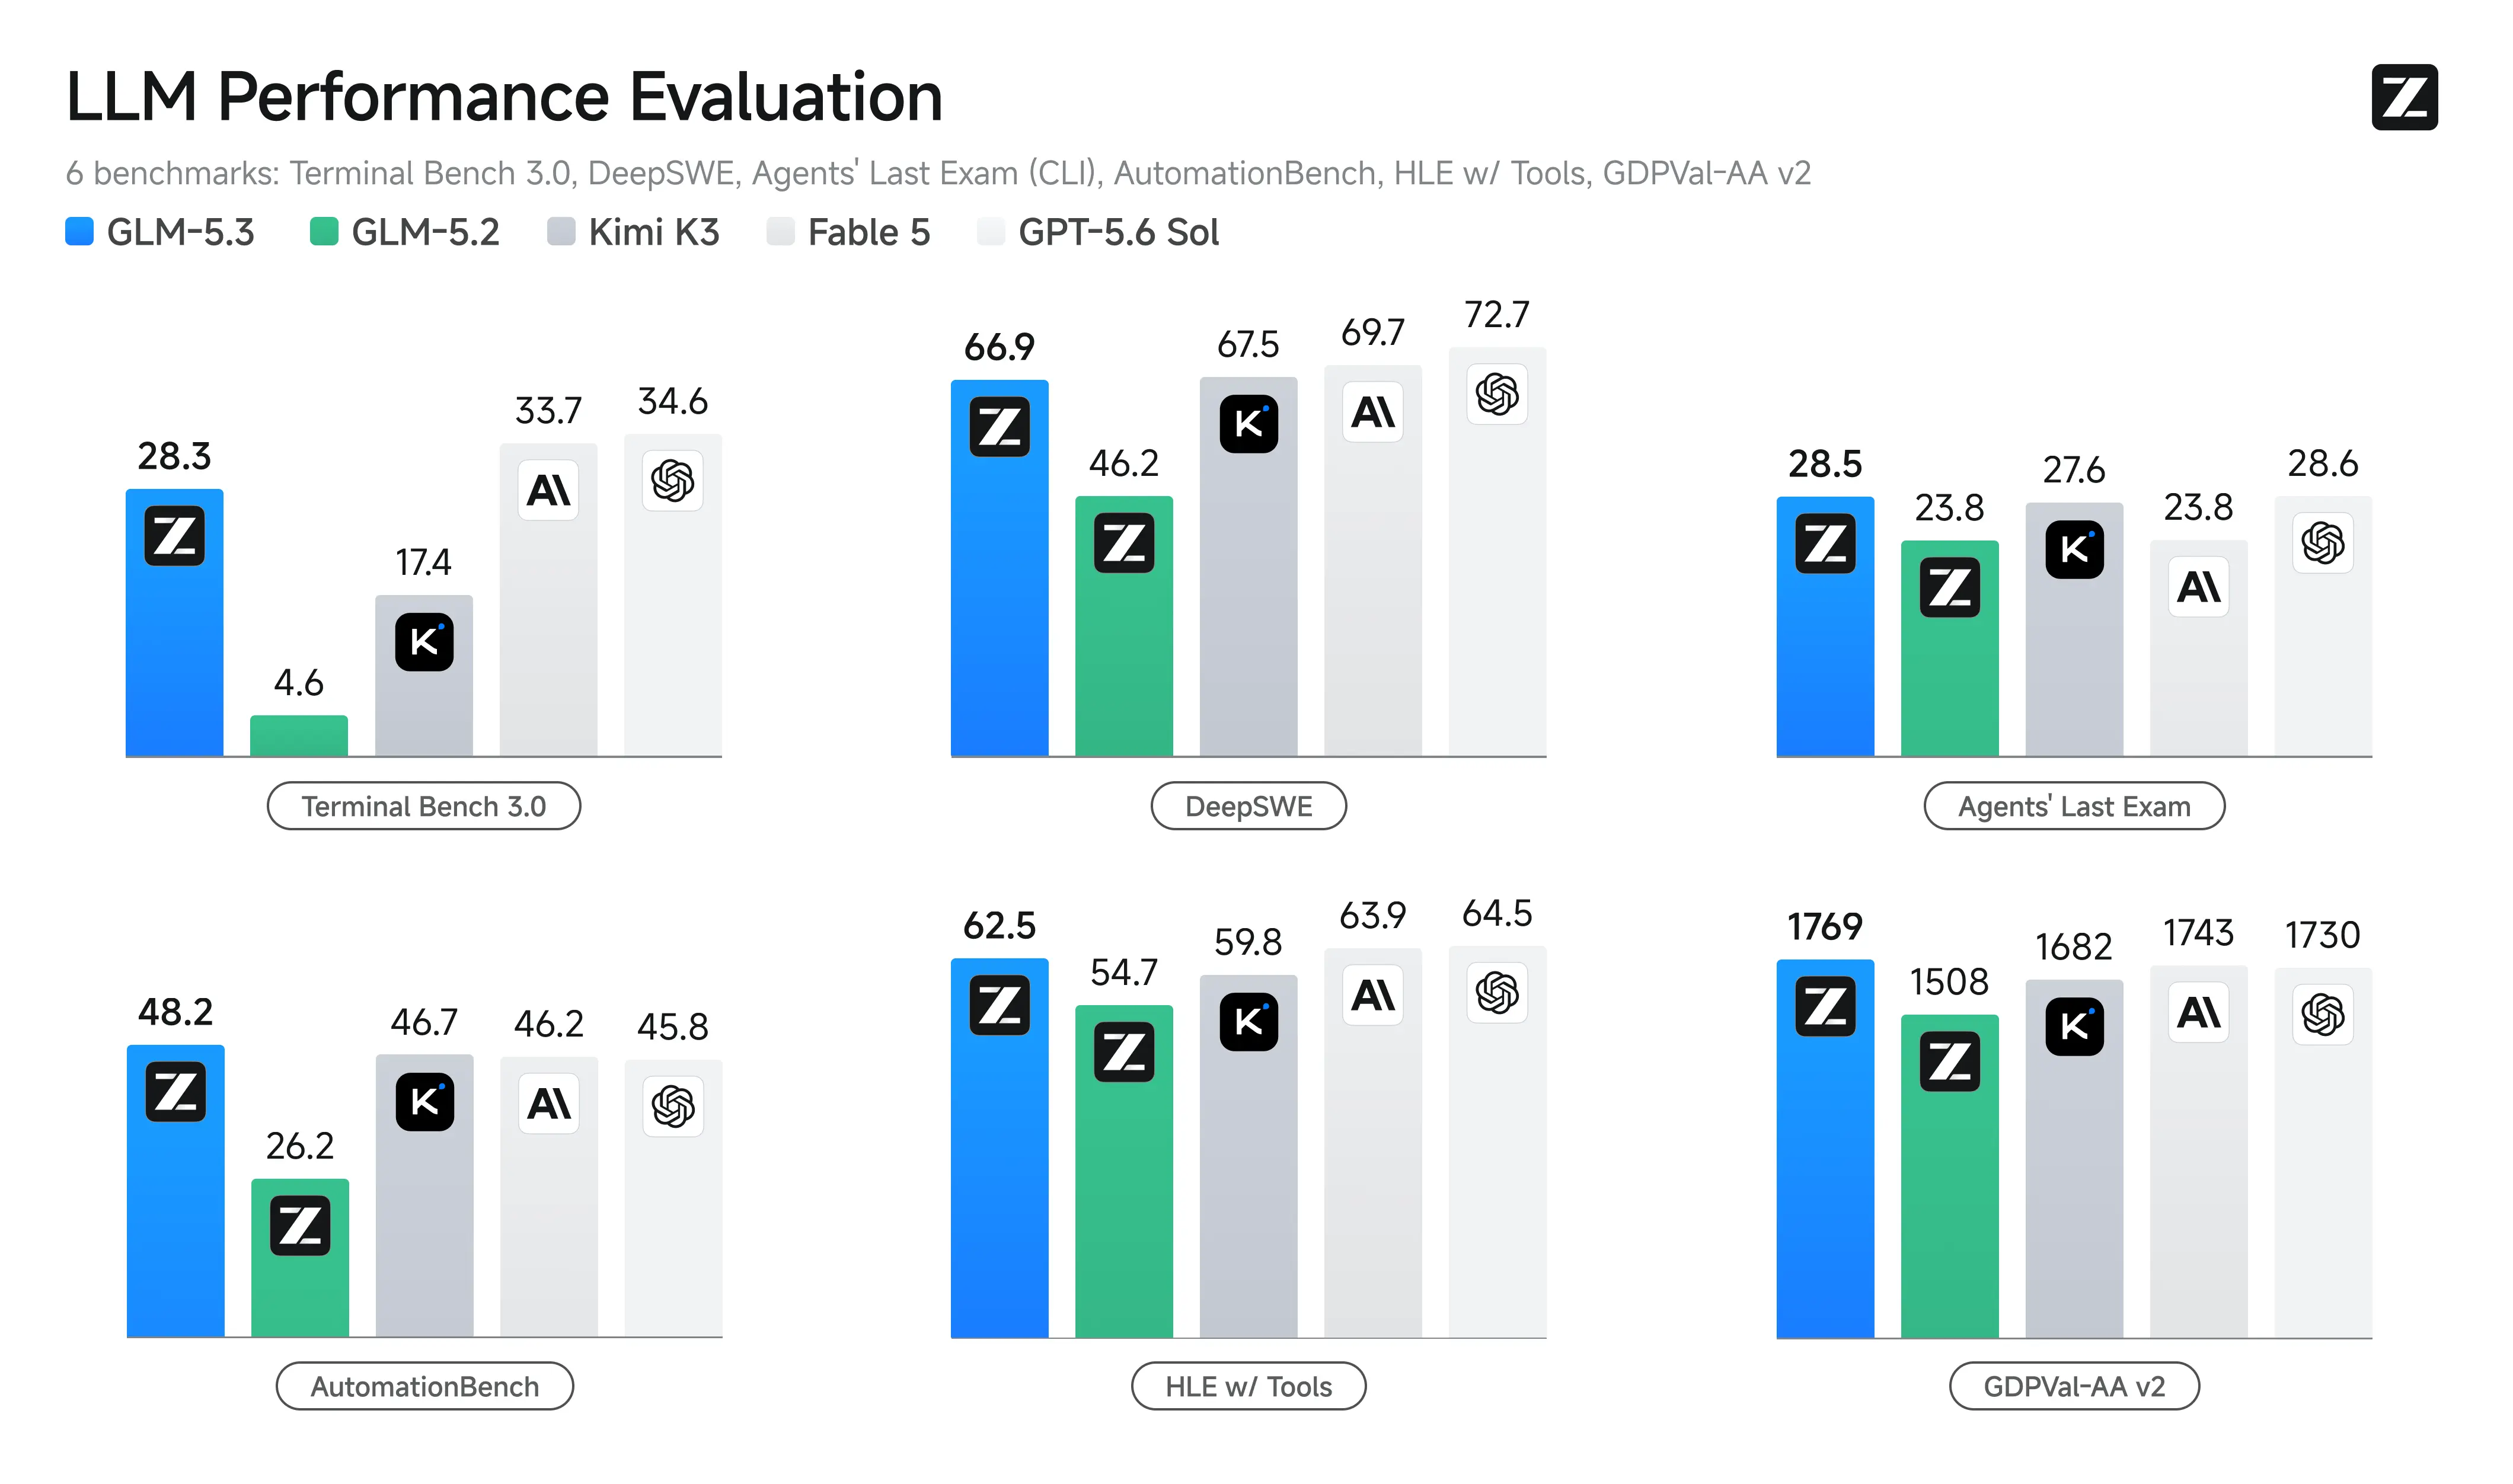
# GLM-5.3 GLM-5.3 uses the same base model as GLM-5.2 — every gain comes from post-training. Compared with GLM-5.2, it is much better at complex coding and long-horizon tasks: + Stronger Coding: GLM-5.3 is the most capable open-weights model for coding, with a 50% improvement over GLM-5.2 on our in-house Z.ai Code Bench. It also achieve open-source SOTA on public benchmarks including Terminal Bench 3.0 and Agents' Last Exam. + Emergent Cyber Capability: As we scaled post-training, cyber capability developed faster than we expected. GLM-5.3 is state of the art on CyberGym for vulnerability discovery, and its gains are largest further up the exploitation chain, where it more than doubles GLM-5.2 on exploitation benchmarks. ## Benchmark ### Serve GLM-5.3 Locally GLM-5.3 supports deployment with the following frameworks. Feel free to try them out: - SGLang — see cookbook - vLLM — see recipes - TokenSpeed — see here - Transformers — see transformers docs - KTransformers — see tutorial - Unsloth — see guide - For deployment on the `Ascend NPU` platform, inference frameworks such as vLLM-Ascend, xLLM and SGLang are supported — see here. ### Note ...

Repository: localaiLicense: other

dfm-mimir:vllm
DFM Mimir is an Apache-2.0, instruction-tuned HRM-Text model from Danish Foundation Models. It has about 1 billion parameters and a 4,096-token context window. The model focuses on Danish and English chat, reasoning, mathematics, and code generation, and uses only permissible post-training data. This entry serves the official BF16 safetensors checkpoint with vLLM.

Repository: localaiLicense: apache-2.0

dirk-qwen3.8-27b-q4
Dirk is a Qwen3.8 27B vision-language model with a concise chat template for agentic coding, reasoning, tool use, and general knowledge tasks. It preserves the model's MTP head for speculative decoding and supports a 262K-token context window. This default entry uses the Q4_K_XL GGUF and F16 vision projector. A choice of Q5_K_XL, Q6_K_XL, and Q8_K_XL builds is available through variants.

Repository: localaiLicense: apache-2.0

qwen3.8-27b-dflash2
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

qwen3.8-27b-heretic-abliterated-uncensored
# Qwen3.8-27B > [!Note] > This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format. > > These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, TokenSpeed, etc. > [!Tip] > For users seeking managed, scalable inference without infrastructure maintenance, the official Qwen API service is provided by Qwen Cloud. > In particular, **Qwen3.8-27B** will be available as a hosted version with more production features, e.g., 1M context length by default, official built-in tools. For more information, please refer to the Qwen3.8-27B Overview. The service is coming soon. Stay tuned for updates. Following the widespread community adoption of the Qwen3.5 and Qwen3.6 series, we are pleased to introduce Qwen3.8, the most capable generation in the Qwen open-model family to date. ...

Repository: localaiLicense: apache-2.0

carbon-3b-q4
Carbon-3B is Hugging Face's 3B-parameter genomic foundation model for DNA and RNA sequence generation, recovery, variant-effect prediction, and motif-perturbation analysis. It supports 32,768 tokens natively and uses a hybrid tokenizer with 6-mer DNA tokens. This default entry uses the Q4_K_M GGUF. A higher-quality Q8_0 build is available as a variant. Prefix DNA sequences with `` and use uppercase A, C, G, and T characters in groups of six.

Repository: localaiLicense: apache-2.0

Page 1 of many